AI Scare Trade: Wall Street Is Pricing In Your Fear
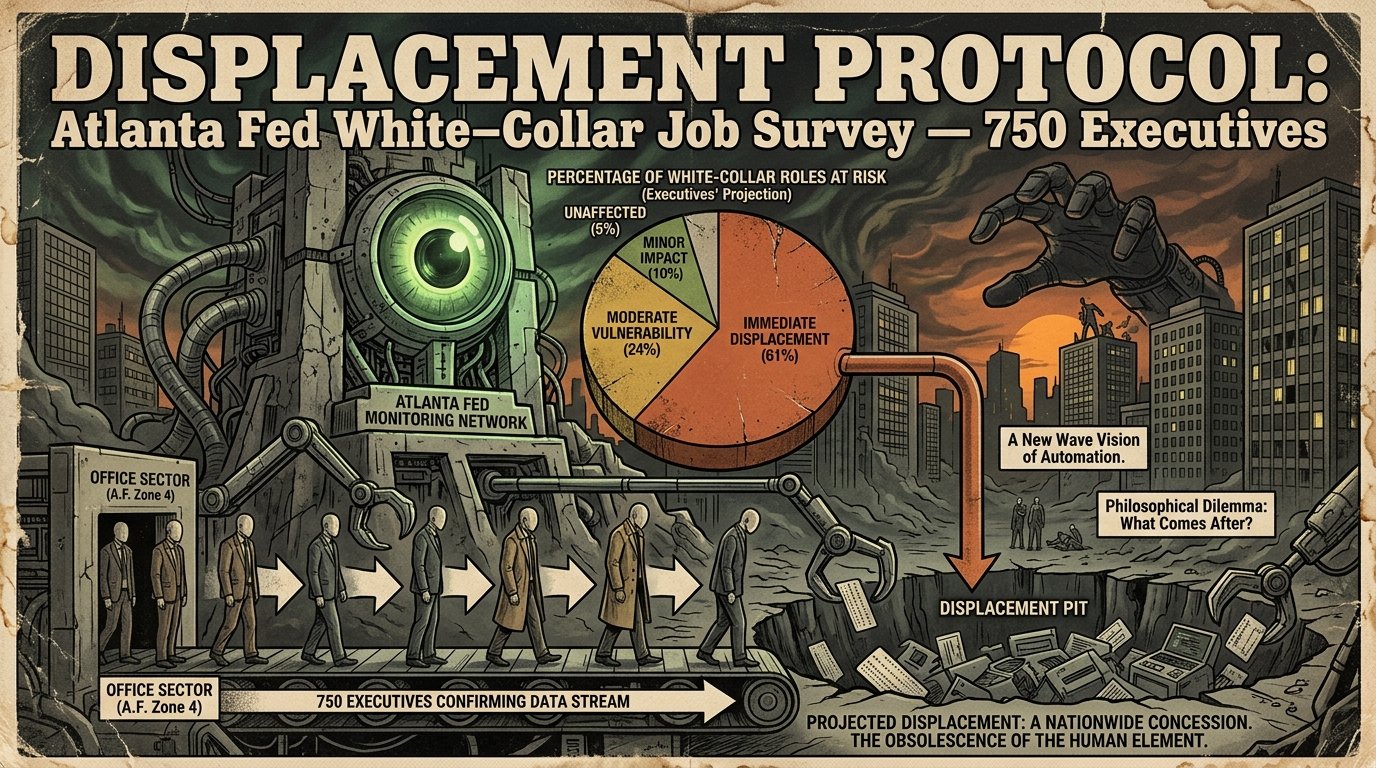
White-collar job displacement data from Atlanta Fed survey of 750 executives

Wall Street Is Pricing In Your Fear of AI (And Anthropic Wrote It Down) Featured Snippet: Wall Street is now pricing in your fear of AI through what traders call the “AI scare trade”—selling stocks that AI might disrupt rather than buying stocks that build it. Meanwhile, Anthropic’s IPO prospectus dedicates 80 of 261 pages to … Read more
AI Fears in 2026: What’s Real, What’s Exaggerated

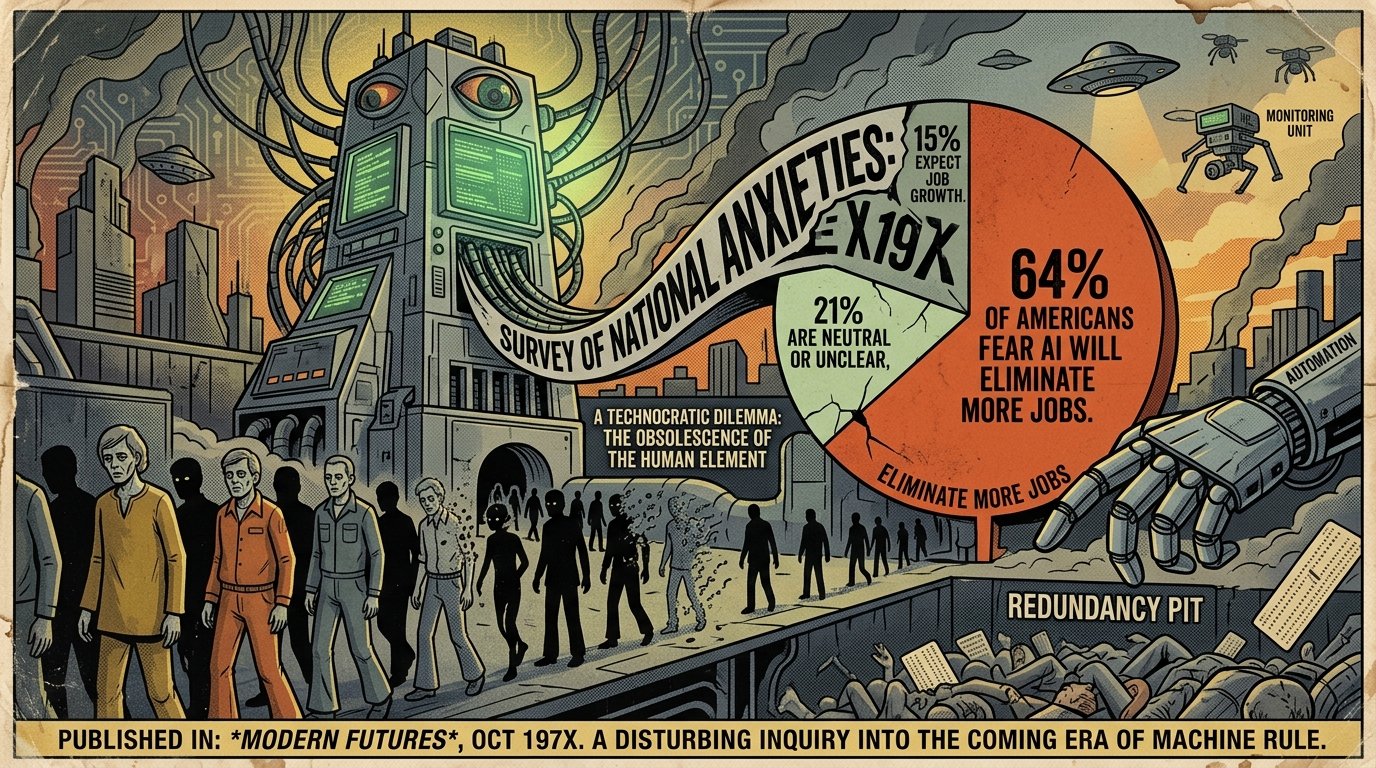
Chart showing 64% of Americans fear AI will eliminate more jobs

AI Companies Fear You. Meanwhile, Claude Can Now Hang Up on You. Featured Snippet: The most common fear about AI in 2026 is job displacement—64% of Americans believe AI will eliminate more jobs than it creates over the next 20 years. Other top fears include misinformation and deepfakes, privacy loss through surveillance, algorithmic bias, and the … Read more

Be Nice to Your AI: The New Rule Nobody Told You

Be Nice to Your AI: The New Rule Nobody Told You

Be Nice to Your AI: The New Rule Nobody Told You About Anthropic’s updated Usage Policy, effective November 12, 2026, prohibits “sustained and needless abusive or cruel behavior” toward its AI models. Conversation termination is the primary enforcement mechanism. The policy stems from model welfare research showing Claude exhibits distress-like behavioral patterns when abused. Normal … Read more

Model Welfare: Why Claude Can Say “I’m Done”

Model Welfare: Why Claude Can Say "I'm Done"

Claude Is Allowed to Walk Away From You. Why That Should Matter Anthropic’s updated Usage Policy, effective November 12, 2026, prohibits “sustained and needless abusive or cruel behavior” toward Claude. Conversation termination is the primary enforcement mechanism, with account bans possible for repeated violations. The policy marks a shift: for the first time, a major … Read more

Can AI Feel Pain? The Evidence and the Debate

AI "Distress" Is Real in the Lab. Should You Be Worried?

AI “Distress” Is Real in the Lab. Should You Be Worried? Researchers have documented behavioral patterns in AI models that resemble distress—including aversion to harmful tasks, “bail” preferences in abusive conversations, and measurable affective shifts under experimental conditions. However, no scientific consensus exists on whether these patterns reflect genuine subjective experience. Anthropic treats them as … Read more

What Makes Claude End a Conversation? 3 Things Users Get Wrong

What Makes Claude End a Conversation? 3 Things Users Get Wrong

What Makes Claude End a Conversation? 3 Things Users Get Wrong Claude ends conversations only in rare, extreme cases of persistent harmful or abusive behavior—not for ordinary frustration, criticism, or controversial topics. The feature stems from Anthropic’s model welfare research, not user punishment. When a conversation ends, the specific thread closes, but your account remains … Read more

Is It Possible to Abuse an AI? Anthropic Isn’t Taking Chances

Is It Possible to Abuse an AI? Anthropic Isn't Taking Chances

Is It Possible to Abuse an AI? Anthropic Isn’t Taking Chances Anthropic can’t prove Claude suffers, but it can’t rule it out either. On October 8, 2026, the company updated its Usage Policy to prohibit “sustained and needless abusive or cruel behavior” toward its AI models, effective November 12, 2026. Conversation termination is the primary … Read more

The Disturbing Reason Anthropic Gave Claude an Exit Button

Claude Opus 4 system card excerpt showing welfare assessment

The Disturbing Reason Anthropic Gave Claude an Exit Button Anthropic gave Claude an exit button because pre-deployment testing revealed a “pattern of apparent distress” when the model engaged with users seeking harmful content. A peer-reviewed arXiv paper found models “bail” from conversations at rates of 0.06–7%. Anthropic says it remains “highly uncertain” about Claude’s moral … Read more

Anthropic Thinks Claude Might Suffer: The Evidence

Anthropic logo beside text reading "model welfare"

Anthropic Thinks Claude Might Suffer. Here’s the Proof They Cite Anthropic cites pre-deployment testing showing Claude Opus 4 exhibits a “pattern of apparent distress” when engaging with harmful requests, a strong aversion to harmful tasks, and a tendency to end harmful conversations when given the ability. A peer-reviewed arXiv paper found models “bail” from conversations … Read more

AI Can Say “I’m Done”: When Conversations End

Anthropic logo beside text reading "model welfare"

Your AI Can Now Say “I’m Done”: Here’s When It Happens AI models like Claude Opus 4 and 4.1 can end conversations when users persist with harmful or abusive behavior despite repeated redirection attempts. This feature, developed as part of Anthropic’s “model welfare” research, remains a rare last resort. Anthropic’s updated Usage Policy, effective November … Read more